Auth Service / recovered
The first action is followed by a successful verification probe. The recovery record marks the attempt as succeeded, and the incident resolves.
Follow the incident timeline →Read the verifying probe outcome →Recovery & operations
Recheck a failure, trigger your recovery endpoint, and verify the result. Bring on-call schedules, runbooks and assigned tasks into the same incident workflow.
Commercial edition. Recovery is off by default; your team configures every action and limit. How a restart hook is checked.
The recovery contract
Recovery can confirm success or leave an incident open. An accepted webhook is never enough.
When an incident opens, the worker probes again before acting. A service that has already recovered needs no trigger.
Vigil sends a signed request to the endpoint you configure. You supply the remediation action and set attempts, cooldown and verification delay.
A successful check confirms the outcome. If verification fails, Vigil retries only within your configured limits.
Exhausted recovery leaves the incident open for a responder. Attempts and verification results remain on the timeline.
Inspect a failed recovery in the tour →Two recorded outcomes
Both examples come from the seeded product tour. Neither is a live monitoring result or a performance benchmark.
The first action is followed by a successful verification probe. The recovery record marks the attempt as succeeded, and the incident resolves.
Follow the incident timeline →Read the verifying probe outcome →Two attempts fail verification. The limit stops further automation and leaves an open incident for a responder.
Follow the handoff →Beyond automatic recovery · Commercial
Some incidents need judgment. Schedules, escalation, runbooks and tasks keep that work attached to the incident.
Define who is on call and when the next responder should be tried. Route incident events to the channels your team uses.
Inspect the escalation setup →Run a bounded sequence against the incident. A step that needs a person creates an assigned task and waits for the response; the run resumes with the result recorded.
Follow a runbook waiting for a person →Open its assigned task →Define availability or latency objectives over a rolling window. Review measured coverage, remaining error budget and the observations behind the result.
Inspect the sample objectives →One incident, end to end
A routing policy decides which channels an event class reaches, and the scope it applies to is stored rather than inferred, so a deleted rule cannot quietly widen an audience. Maintenance windows suppress by reading timestamps, not by flipping state, and they are DST-safe.
On-call rotas and escalation ladders decide who is woken and when the next person is tried. Delivery is durable: attempts are append-only, retries walk from about a minute to six hours, and a lease is fenced so two workers cannot both own one message.
Bounded steps against the incident, from a typed action registry. Two of those actions involve a person, and when one runs the whole run suspends rather than pretending to continue.
The hand-over becomes a task with a deadline and an owner. The answer that comes back is stored beside the step that asked for it, and the run resumes when the task is completed or cancelled, or when the step it waits on reaches its own deadline.
A status update posts from the incident screen to the public page, an objective's error budget is computed from the same observations the incident came from, and the postmortem is drafted from the real timeline instead of a blank page.

runbook runevery step keeps what it sent, what came back, and what it verified afterwards
Who is woken
Escalation steps reach people by email, SMS or voice call. Email is always available; SMS and voice route through your own Twilio account, and steps on channels you have not configured are logged rather than silently skipped.
Every message has a ledger: queue pressure, attempts spent, when the next retry is due, and the reason it stopped. An attempt that never reported an outcome is visible as exactly that rather than counted as a success.
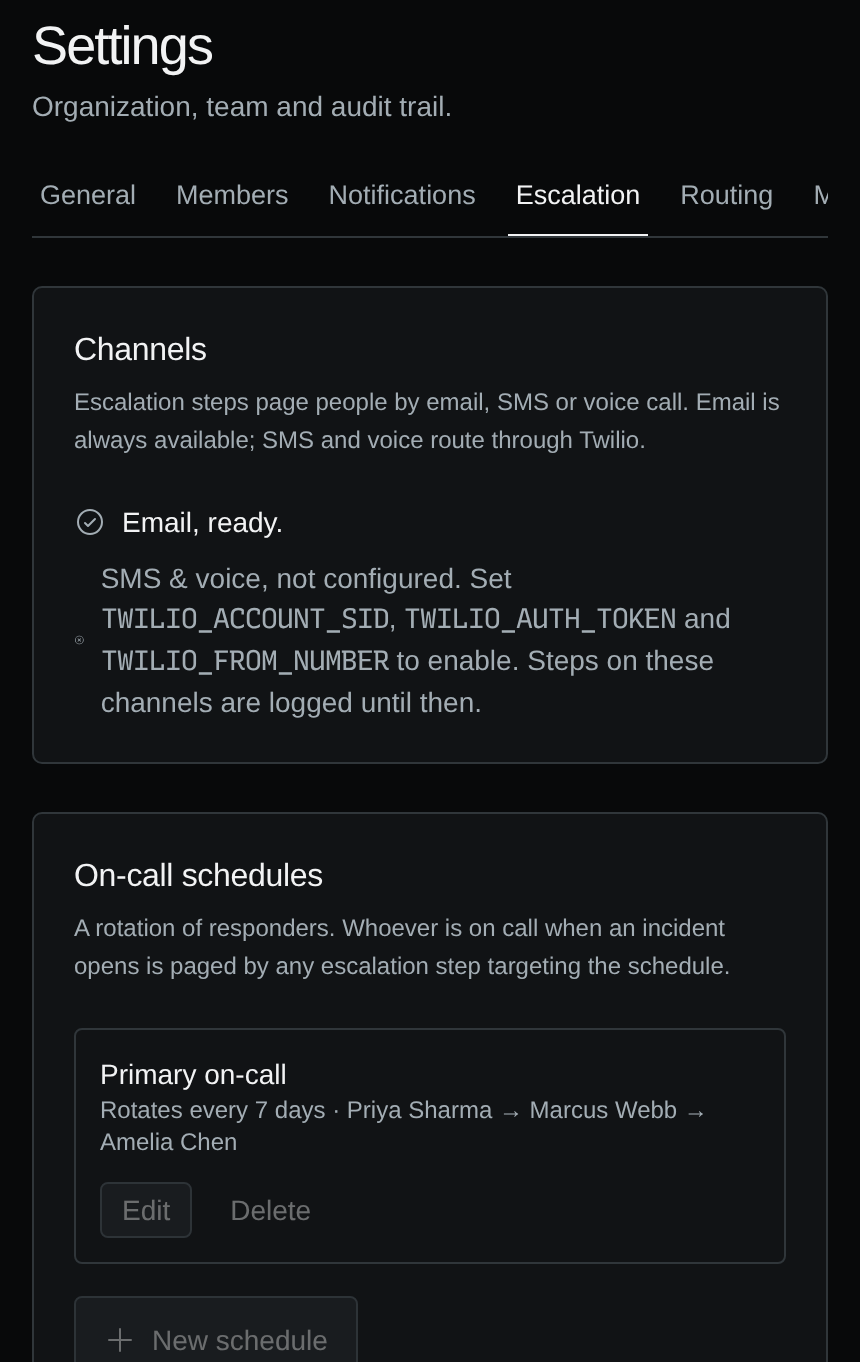
escalationrota, ladder, and what each step may use
Objectives
An objective measures the same observations the incidents came from. Compliance over the window, how much budget is left, and the burn windows that are firing, computed from one source of truth rather than from a second pipeline that drifts.

objectivethe budget is spent, and the burn windows say how fast it went
Running it
The supported path is Bash and Docker Compose.
vigilctl checks real health rather than
container liveness, validates a backup archive before it
moves anything, and refuses a state it cannot own safely
rather than guessing at it.
Nothing rolls back on its own. A rollback undoes code and database together, and an operator asks for it.
All of this runs on a server you supply.
Your infrastructure. Your record.